Blind monitoring
You discover the outage when a customer complains.
EXPERTISE · PLATFORMS & OPERATIONS
Monitoring, observability, backups, disaster recovery and managed services: we keep your services up and running.
WHY IT’S CRITICAL
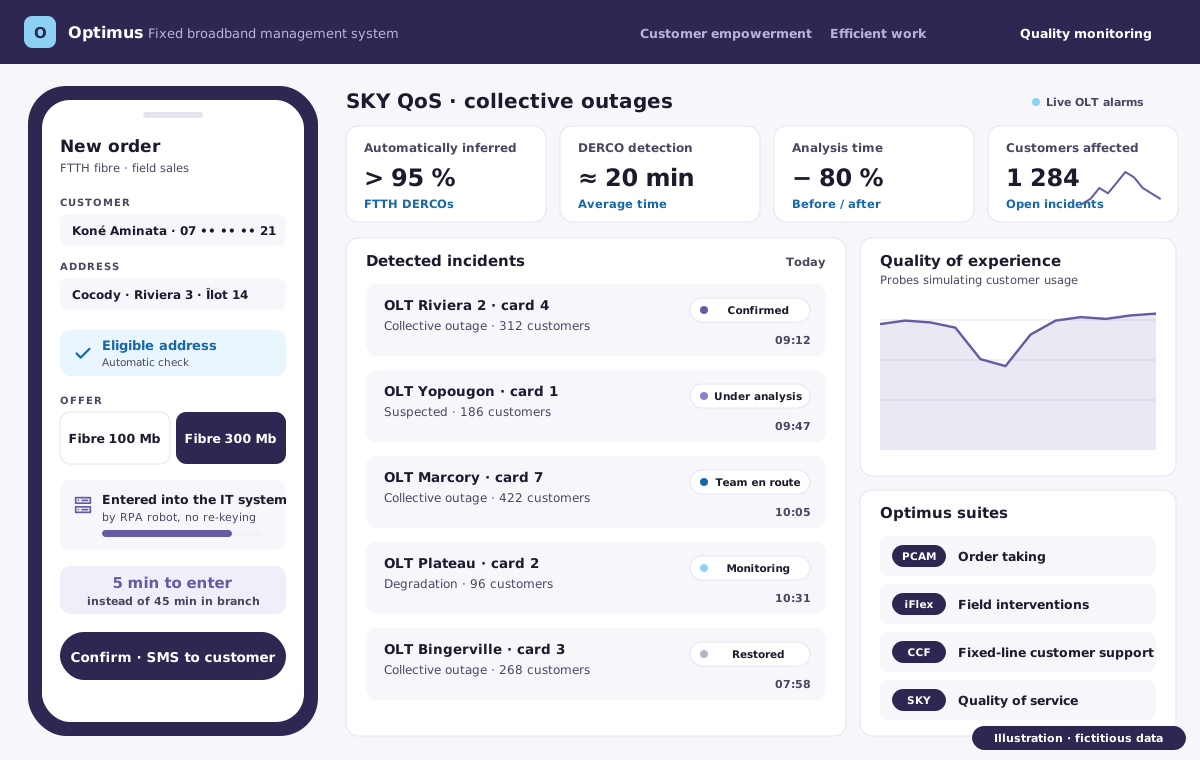
We make your services observable and we run them. Not just “is the server responding?”, but “is the service working for the customer?”: response times, error rates, availability.
As managed services, we commit to service levels that are defined and tracked together.
THE CHALLENGES
You discover the outage when a customer complains.
The backup exists; the restore has never been checked.
Fibre, VPN and Wi-Fi authentication managed tool by tool.
WHAT WE DO
Services that combine to fit your context, from scoping to operations.
Infrastructure, applications and customer journeys.
Collection and analysis of application logs.
Scheduled backups and regular restore tests.
Business continuity and disaster recovery plans, failover drills.
Subscriber and user authentication.
Operations, level 2 and 3 support, maintenance under service commitments.
OUR APPROACH
Critical services, tools in place, recent incidents.
Service mapEnd-to-end monitoring, meaningful alerts.
Monitoring dashboardsIncident handling and maintenance in operational condition.
Service reportsIncident analysis, preventive actions.
Improvement planWHAT YOU GET
Scope, responsibilities and acceptance criteria are defined during scoping.
Monitoring dashboards and alertsFocused on the service delivered.
Backup policyAnd restore test reports.
Documented and tested DRPWith failover drills.
Periodic service reportsAvailability, incidents, actions.
TECHNICAL ENVIRONMENT
Around thirty open-source and vendor solutions, chosen to fit your context. Technologies are confirmed during scoping.
FREQUENTLY ASKED QUESTIONS
Yes, after a reversibility phase: inventory, documentation, onboarding into monitoring, then a gradual transfer of responsibilities.
They are defined with you according to the criticality of each service: coverage hours, response and restoration times, reporting.
We favour proven open-source tools and adapt to your existing tooling where it is already in place.
GO FURTHER
GETTING STARTED
WHEN TO CALL US
A critical platform to take over, a provider to replace, recurring incidents.
FIRST ENGAGEMENT
A prepared operations takeover: platform audit, transfer plan and service levels.
INDICATIVE DURATION
4 to 6 weeks
WHAT WE NEED FROM YOU
Existing documentation, administration access and incident history.